Features
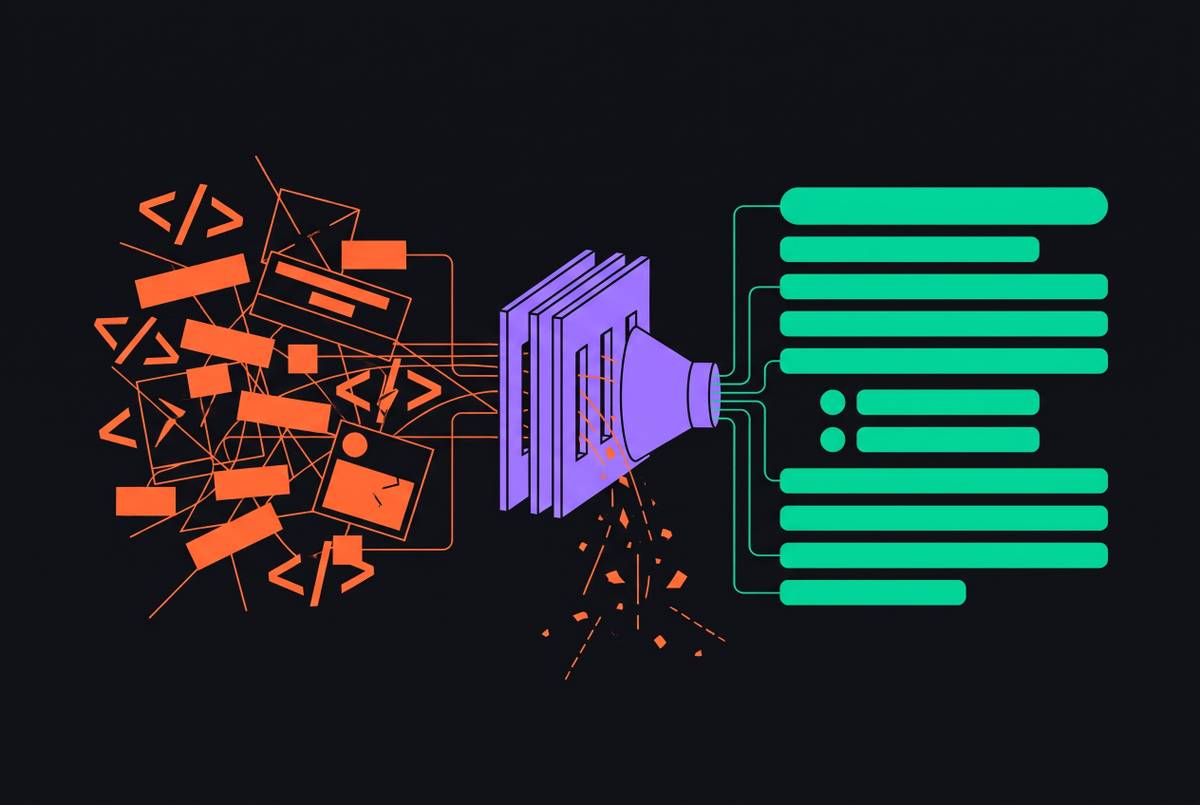
Cleaning Raw HTML Into LLM-Ready Text Without Losing Structure
A three-stage pipeline preserves semantic structure while removing noise that wastes LLM context.
Elena Fontaine
· 8 min read
A three-stage pipeline preserves semantic structure while removing noise that wastes LLM context.
Four hidden layers bind agents to search providers and compound the cost of switching.
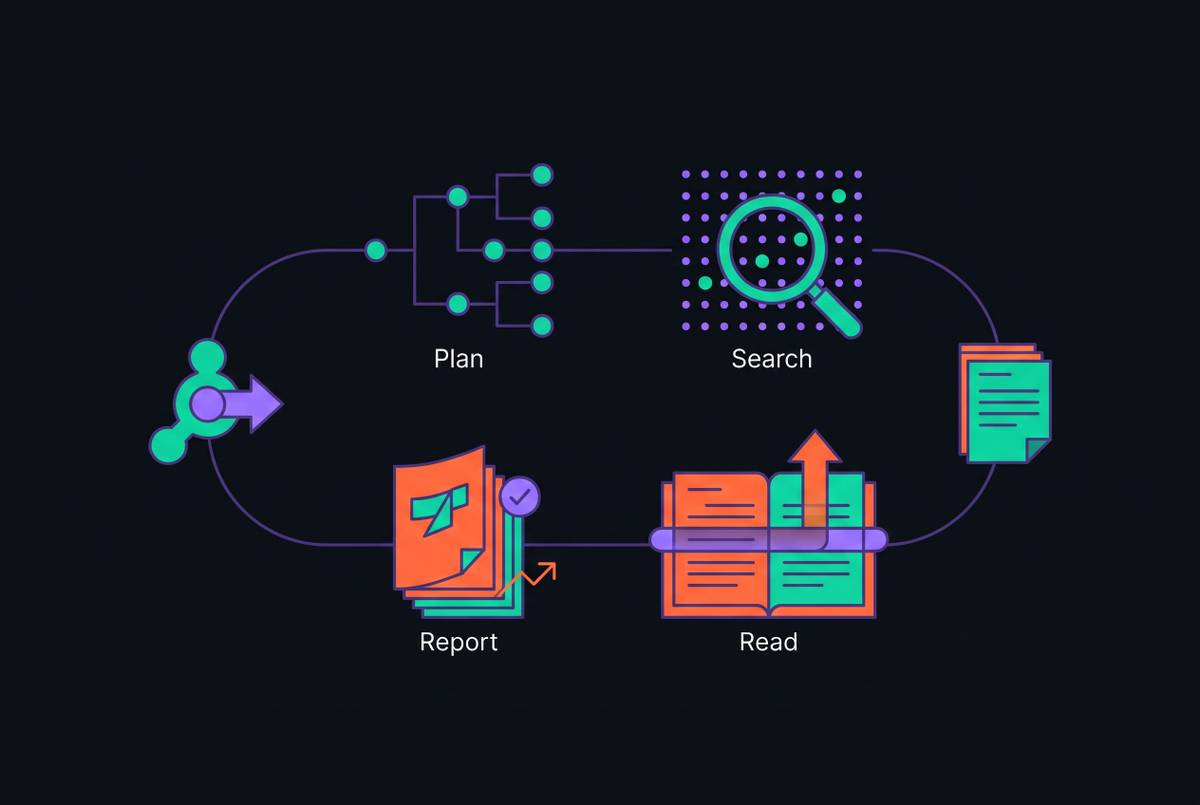
Agents need five separate stages to produce research reports readers can verify.
Cleaning data before inference matters more than expanding context window size.
Web chunking strategies must vary by source structure, not rely on universal token counts.
Rigorous evaluation requires decomposing claims and connecting metrics to deployment gates.
Balancing document freshness and semantic relevance determines retrieval accuracy.
Routing queries to the right source matters more than choosing between them.
Comparing AI search API prices requires measuring cost per completed task, not just rate cards.
Four design principles make research agents work across healthcare, legal, and supply chain.
Financial AI needs schemas with validation and citations, not just formatted JSON.
Traceability to live sources matters more than model accuracy in financial AI.