Context Window Optimization for Grounded LLM Responses
Cleaning data before inference matters more than expanding context window size.
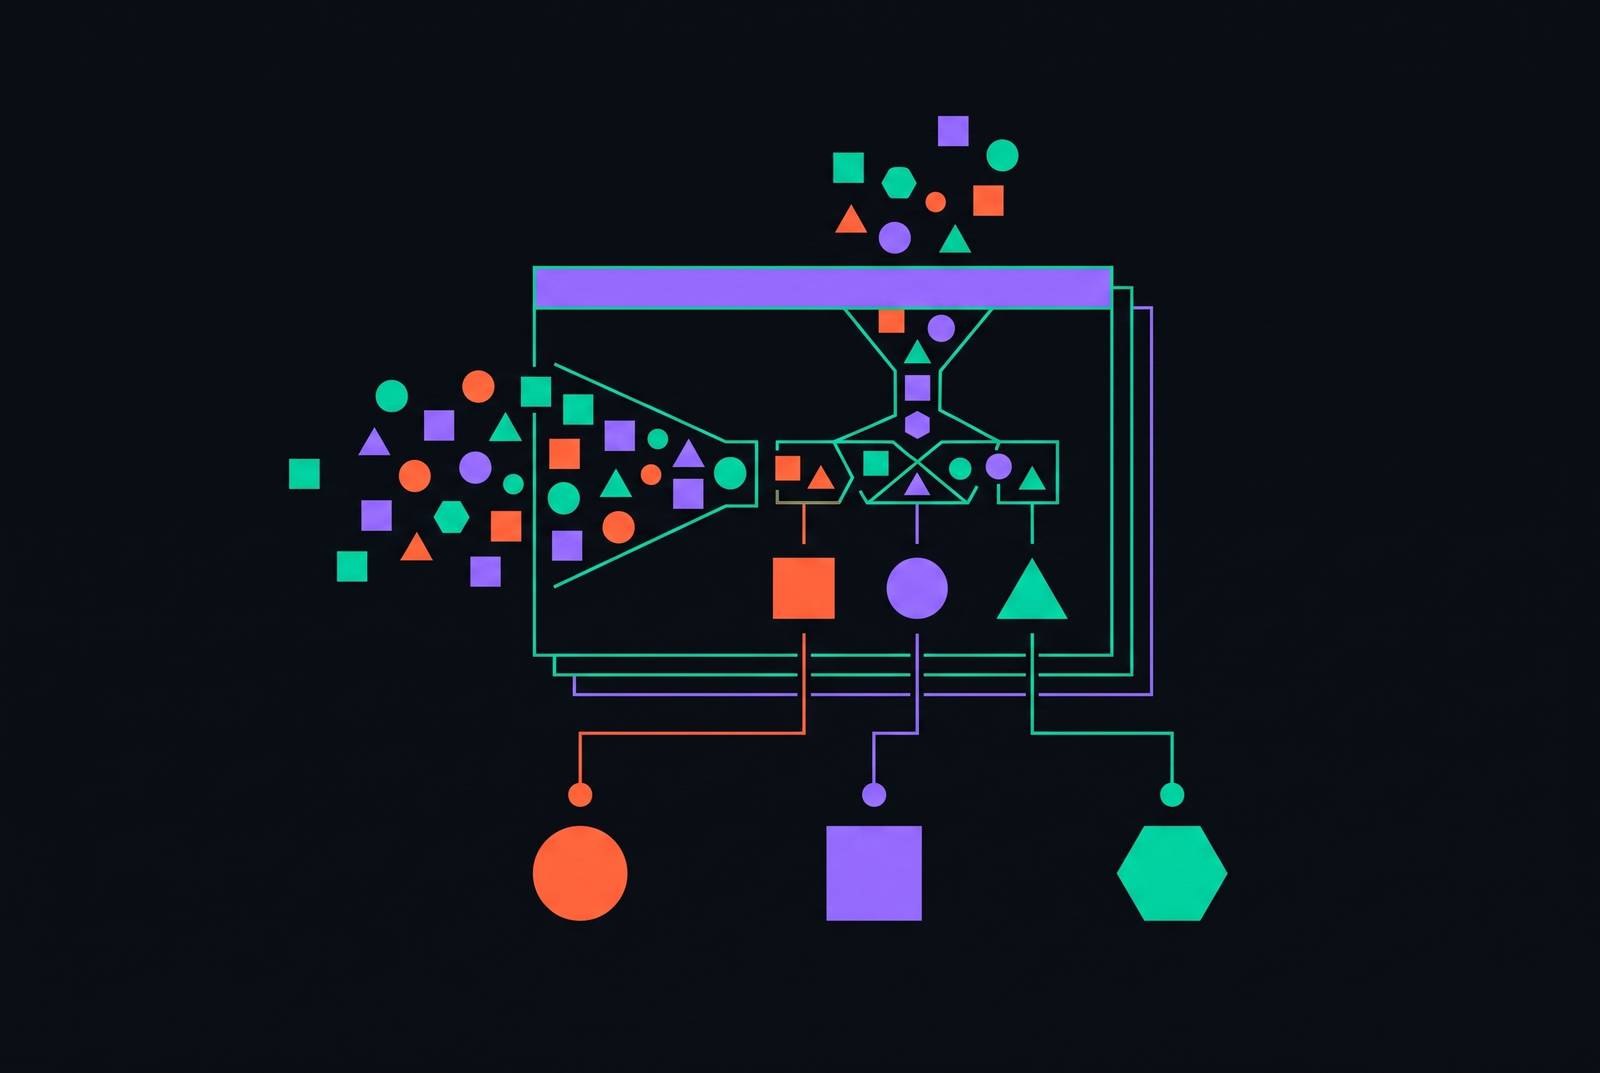
Context window optimization for grounded LLM responses is an upstream data quality problem before it is a model-capacity problem. Larger windows help only when the evidence inside them is useful. The work that improves accuracy starts before inference, with structured extraction, provenance tagging, deduplication, and noise filtering, then continues through retrieval and runtime context management.
Why raw context window size is no longer the primary accuracy lever
“Just give the model more context” is an understandable starting point. If an answer has too little evidence, adding more documents seems like the obvious fix. In production, however, additional documents bring irrelevant material as well as facts, and models do not reliably ignore the difference. More capacity can make an answer worse.
The context window is the total token budget for a single model call, shared by system instructions, retrieved documents, conversation history, and the user query. Models pay disproportionate attention to the beginning and end, leaving evidence buried in the middle less likely to receive attention. What, then, does a larger window actually guarantee? It provides room. In a grounded architecture, the model becomes a reader and summarizer constrained to supplied evidence rather than an oracle drawing on parametric memory, so evidence quality bounds answer quality.
How noise enters the context and what it costs
Raw HTML is a primary route for noise. Navigation chrome, cookie banners, inline scripts, and repeated footer blocks use up tokens without helping answer the question. Converting HTML to markdown before injection often cuts agent token counts by more than half because markdown preserves headings, lists, and links while discarding markup and page machinery.
Structural noise also creates factual ambiguity. A display price, a crossed-out original price, and a shipping fee may share similar tag patterns in raw markup. If extraction fails to distinguish their roles, the model can choose a number that appears on the page but does not answer the question. The error begins before the answer is written.
When the same header and footer appear across hundreds of pages, their token sequences inflate embedding input while making unrelated documents look more alike. Retrieval then becomes less discriminating, and the model receives weaker evidence at greater expense. Tokens use up both money and space in the context window. Filtering at ingestion therefore addresses a chain of failures that would otherwise require separate repairs later.
The pre-LLM pipeline as the real engineering surface
The architectural shift is to treat extraction, format conversion, provenance, and deduplication as the foundation of grounding. Retrieval-augmented generation, chunking, and contextual compression all depend on that foundation. They cannot make noisy source material safe to trust just by choosing, splitting, or shortening it. Quality must enter before those operations begin.
The pipeline runs from query to search API, fetch, cascade routing, context packet assembly, LLM gateway, numeric verification, and citations. Each stage needs a quality gate because a failure passed forward degrades what follows. An extraction failure passed on as an empty string, for example, can reach the embedder without a clear application error and harm retrieval without anyone noticing. The absence of a crash proves very little.
For builders, the immediate requirement is to validate every extraction output against a typed schema before embedding. When a malformed record gets into the index, it causes failures far from where it went wrong, which makes the cause hard to find. The payoff is concrete, including fewer wrong answers, access to current facts, and citations that users can follow to the evidence.
Structured extraction and model-ready content
Extraction works best as an escalation path. Tier 1 uses a static fetch with heuristic boilerplate stripping, offering the lowest latency and cost for clean article pages. It succeeds when the content-density score clears the quality threshold. Otherwise, the cascade moves to Tier 2, which applies density and block scoring with reconstruction when extraction is sparse or the token count falls outside the expected distribution for that content type. Each escalation needs evidence that the cheaper path failed.
Tier 3 adds headless browser rendering for pages that need JavaScript execution. JavaScript-detection flags in response headers, low content density, and extraction failure tokens help the system choose where to route a page. Rendering has much higher latency and cost, so the system uses it as a last resort before Tier 4. That last tier uses LLM extraction when all earlier quality gates fail, giving the highest accuracy at a cost that is orders-of-magnitude greater.
Every extracted block then faces three checks. These are verbatim coverage rate (the ratio of extracted tokens appearing verbatim in the raw HTML), a token-count distribution check, and a block-level coverage threshold. Failures move to the next tier or a logged dead-letter store, never downstream. Short retention of raw HTML with the extraction output makes regressions replayable, allowing a team to distinguish a site change from a pipeline bug.
Provenance tagging and the context packet schema
An answer needs more than clean text for someone to audit it. A retrieved fact also needs an identifiable source snapshot, a retrieval time, and a record of how extraction occurred. Without those details, how can a system check that facts are fresh or look into records that disagree?
A typed context packet contains contentHash, source_url, fetched_at, extraction_tier, and verbatim_coverage. The contentHash ties the content to its exact snapshot and supports deduplication and replay. The fetched_at field enables maximum-age policies at retrieval time, while extraction_tier distinguishes static fetching from later escalation. The remaining fields connect the text to its source and record its verbatim coverage.
At response time, the prompt version, selected context IDs, and citation URLs belong in the same audit row. This links the answer to the evidence supplied during generation. A correct-looking citation alone is not enough. Citation post-rationalization occurs when a source supports an answer without faithfully reflecting how the model formed it, and provenance makes that mismatch open to investigation. It does not make every citation faithful by itself.
Deduplication and chunking before the embedding layer
Repeated boilerplate can distort the geometry that retrieval depends on. Shared structural chrome pulls embeddings toward a common centroid, making chunks from different pages appear similar regardless of the query. The system can then retrieve the right shape of answer with the wrong content. Deduplication must precede admission to the vector index because removing repetition afterward leaves the earlier embedding work and index contamination unaddressed.
MinHash or SimHash can catch near-duplicate chunks at ingestion before embedding. Chunk boundaries must also keep the meaning intact by following paragraph breaks and heading transitions. A moderate token range keeps chunks manageable, while the nearest heading and structured metadata, including date, author, and URL, remain chunk-level fields. Sentences should never be split across boundaries. A divided sentence loses coherence in both halves.
The benefit extends beyond more relevant answers. Clean chunks with no repeated content cost less to embed and store because the pipeline stops paying for the same page furniture over and over. Post-ingestion centroid drift monitoring then provides a check on whether boilerplate is still leaking through extraction. If new content consistently pulls embeddings toward a shared centroid, that signal points back upstream before degraded retrieval reaches users.
Context management across long-horizon agent sessions
Long-horizon agents accumulate conversation turns and observations, creating a runtime problem inside the model boundary that complements the ingestion pipeline. The pipeline cleans what enters, while context management governs what stays. Yet fewer tokens do not automatically mean cheaper inference, because pruning or rewriting earlier history can break cached prompt prefixes.
Compaction has two costs to account for. Summarization itself requires inference, and changes to the sequence layout can invalidate cache reuse. Production traces show less cache reuse around compaction events, so cutting too many tokens can add more to the cost of inference than it saves. How much history can be removed depends on how removal affects both task continuity and cache continuity.
TokenPilot by Xu et al. addresses this through a dual-granularity framework. Its Ingestion-Aware Compaction stabilizes prompt prefixes and removes environmental noise at warm-up rather than retroactively rewriting an existing cache. Its Lifecycle-Aware Eviction monitors the residual utility of context segments and defers structural eviction until task relevance expires. TokenPilot reports substantial cost reductions on PinchBench and Claw-Eval in isolated and continuous modes while maintaining competitive performance.
Why the "just add search" shortcut fails in production
If fresh evidence is the goal, why not simply enable web search? Search helps with knowledge staleness by giving the model current information, but the model can still misuse what it finds. A grounded answer can still retrieve the wrong page, miss a critical source, overstate a citation, or ignore the supplied context. Errors in how the model reasons over retrieved content need their own fixes.
Reference errors and content grounding errors each need their own checks. A model can point to the correct source while misrepresenting what that source says. How well extraction works and how the context is structured affect that second kind of error in ways that search access alone cannot fix. A citation is a route to inspection.
The RAG-OSINT evaluation found high precision-at-5, high citation accuracy, and a 4% hallucination rate. For builders, the lesson is to evaluate search infrastructure by source recall, freshness, full-page extraction, JavaScript and document support, citation provenance, and latency. Search API selection shapes the evidence supply, but the surrounding pipeline must turn that supply into an accurate answer.
What a production-ready grounded pipeline looks like end to end
In a production architecture, each stage’s output schema is the input contract for the next stage. Search and fetch find live URLs for the query before prompt assembly and return clean extracted content in place of raw HTML or snippets alone. Where extraction fails its gates, the cascade escalates from heuristics through density scoring and JavaScript rendering to LLM fallback, with spending caps at the higher tiers.
Before embedding, a MinHash pass removes near-duplicates and semantic-boundary chunking preserves headings and metadata. Typed context packets retain contentHash, source_url, fetched_at, extraction_tier, and verbatim_coverage through retrieval and assembly. After generation, numeric verification rejects answers whose numbers are absent from the retrieved context, and citation plumbing ties each reference to its audit row. Observability completes the architecture through service-level indicators that expose silent extraction failures and post-ingestion monitoring for centroid drift. These controls cover different failure modes.
You.com’s Web Search API, Answer API, Contents API, Research API, and Finance Research API provide infrastructure for this work through real-time web search, structured extraction, and grounded research with cited, verifiable sources at low latency. Handling extraction, provenance, and freshness natively removes work that a team would otherwise build and maintain. The Research API held the top position on DeepSearchQA at its initial launch but has since been surpassed on the current leaderboard. That qualification is part of the credential because the accuracy claim is publicly measurable.
For financial research, the same architecture faces a particularly concrete test. Numbers must be reconciled to sources and cited. The Finance Research API is first on the T2 (Simple Historical Lookup) sub-task of the FinSearchComp T2 (Simple Historical) sub-benchmark. That result covers one task, while production still needs a way to trace every numerical claim all the way back to the retrieved evidence that supports it.