Cleaning Raw HTML Into LLM-Ready Text Without Losing Structure
A three-stage pipeline preserves semantic structure while removing noise that wastes LLM context.
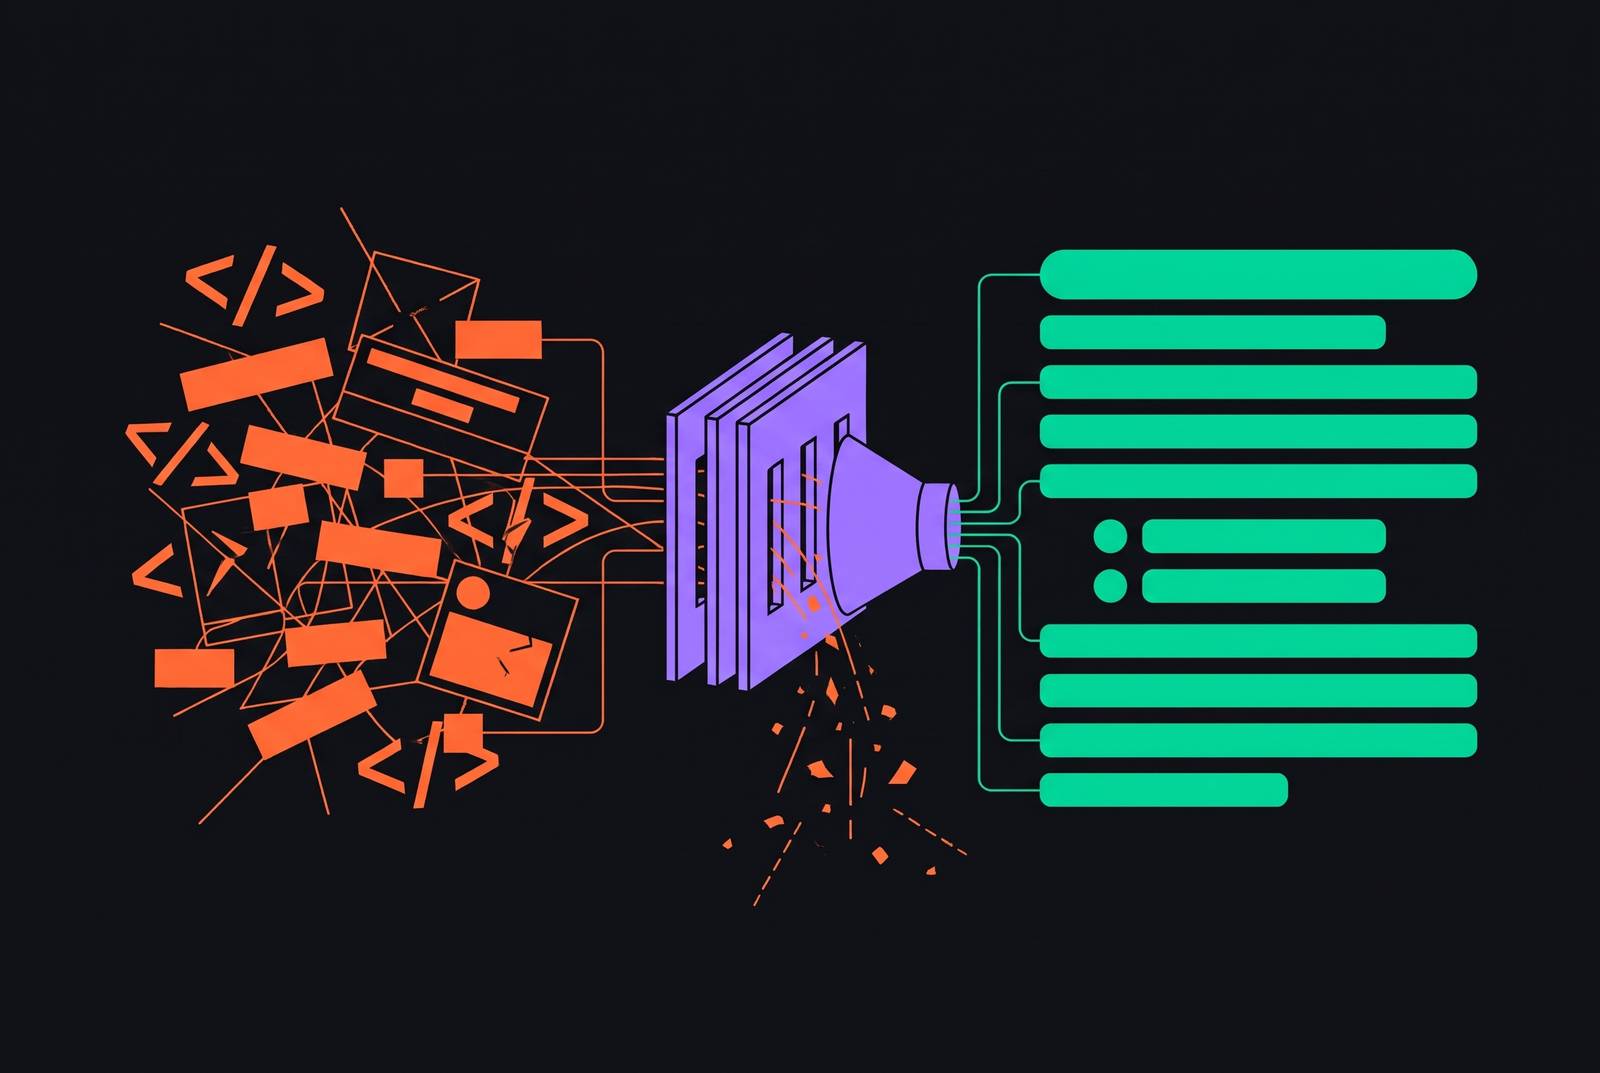
Cleaning raw HTML into LLM-ready text takes a pipeline designed to do more than strip tags. Noise removal, structure normalization, and format conversion each protect a different part of the evidence. Keeping those jobs distinct lets a system discard page clutter without losing the relationships that make the remaining text useful, interpretable, and traceable.
Why raw HTML is a poor direct input for LLMs
A scraped page mixes prose with scripts, inline styles, tracking pixels, navigation, cookie banners, and ads. All of it consumes the model’s context budget. Inline JavaScript introduces code tokens into the same input as factual evidence, while site-specific DOM layouts force the model to infer where a price or publication date belongs. Yet the largest block of markup need not contain the most useful information. When boilerplate dilutes retrieved evidence, a RAG system can produce confident text that the source does not support. Trust in an answer starts before generation, especially when the answer must be traced to a specific passage.
Why this is a multi-stage pipeline problem, not a parsing step
Stage 1 removes noise that cannot contribute to the intended factual answer. Stage 2 normalizes the surviving structure, including heading levels, list nesting, tables, and paragraph boundaries. Stage 3 serializes that structure into the format the downstream consumer needs. These are separate decisions, even when one implementation performs them together. Collapsing them into “strip and ingest” makes it difficult to tell whether a missing relationship disappeared during extraction or conversion.
A university pipeline paper illustrates why those intermediate states are important. Its analysis of EU Digital Fairness Act consultation submissions processed PDFs and web-form responses, producing 15,368 topic annotations grounded in 20,951 verbatim evidence quotes. Every extraction was traceable to its source paragraph. Although this was not solely an HTML-cleaning task, its requirements expose the same architectural constraint. Verbatim grounding, full traceability, and transparency require inspectable transformations rather than a black box whose only visible result is the final text.
Stage 1 in practice: what to remove and how to identify it reliably
Noise removal starts by sorting clutter into categories, because each kind needs a different test. Scripts, styles, and base64-encoded tracking pixels can be removed entirely. Cookie notices, social-sharing widgets, and related-article blocks need rules that target each element more carefully. Their tags alone do not identify their purpose. Boilerplate prose presents a third problem, as legal disclaimers, copyright notices, and newsletter invitations remain grammatical and readable after ordinary tag stripping. When factual retrieval has no need for those elements, output that looks clean can still have little useful information.
The boundary is not simply “content versus markup.” An aggressive rule targeting a class name or ID can remove legitimate material in a reused layout container, and a site redesign can invalidate that rule. Under-removal pollutes the evidence, while over-removal deletes it. This makes categorical removal logic more reliable than a generic attempt to flatten the page. It also makes the intended retrieval task part of the definition of noise.
Pages that are mostly navigation or JavaScript may shrink to only a few dozen words after cleaning, with too little useful content left for embedding. A word-count or token-count threshold can drop those pages before they enter the corpus. A text-cleaning service exposes word count and processing time with its cleaned text, providing metadata for this kind of post-extraction filter. Length can show that an extraction is almost empty, but it cannot show whether the text is relevant.
Stage 2 in practice: preserving semantic structure rather than discarding it
Once the clutter is gone, what relationships must survive? Headings distinguish a main topic from a sub-question, while ordered-list numbering distinguishes a sequence from a collection. Flattening either into undifferentiated prose removes information a retriever could use to interpret a passage. Tables make the loss especially concrete. A value belongs to both a row and a column, and a flat string of cell contents can sever those associations. Code blocks also need to stay separate so that examples do not run into the instructions around them.
The consultation pipeline’s verbatim-grounding requirement depends on retaining the source units to which extracted claims refer. Readability alone cannot supply that provenance after the boundaries disappear. Structure normalization therefore has to preserve both how content is organized and where evidence can be located. Format conversion can only encode relationships that reach it intact.
Extractor choice determines much of what reaches this stage. An extractor comparison study found that, under the same post-extraction curation pipeline, a substantial share of surviving pages were uniquely kept by just one of three tested extractors. For pretraining-scale work, multi-extractor ensembles offer a way to improve coverage, with disagreement serving as a signal of extraction difficulty. No single extractor reliably captures the full content of every page.
Stage 3: choosing the right output format for the downstream consumer
Markdown is a practical default for many RAG pipelines because it expresses common document relationships with little markup. Heading levels become heading markers, lists retain their markers, and links retain readable text. HTML-to-Markdown libraries can convert the content, while an API can return Markdown directly. Conversion is not cleaning by itself. If noise removal has not happened first, navigation text and skip-link clutter can stay in a Markdown document even when its format is correct.
Pruned HTML is another option when the quality of an answer depends on keeping the structure intact. A research approach, presented at a web research conference, cleans and compresses HTML before applying a two-step block-tree-based pruning strategy to shorten it while minimizing information loss. It outperformed plain-text-based post-retrieval processes across six QA datasets. Its advantage rests on retaining structure that plain text discards. The DOM hierarchy can also be used for structural annotation, including supervision based on element paths. The trade-off is greater pruning complexity, with tooling still at research stage at the time of publication.
Typed JSON answers a different downstream need. If a database or comparison engine requires prices, dates, ratings, or booleans, Markdown leaves another extraction and type-conversion task unfinished. A schema-first route defines the expected fields and types, then returns numeric, boolean, and string values ready for use. That route complements Markdown pipelines. The consumer’s need for a readable evidence document, structural relationships, or typed fields for arithmetic and sorting determines the format.
When an LLM cleanup pass improves output that prior stages miss
Some unwanted text is structurally indistinguishable from useful prose. An unrelated author biography or promotional callout may make it through removal rules, structure normalization, and format conversion because both the content and its container are valid. An optional LLM pass can assess that residual semantic noise. Its role is narrower than extracting the original page. It works on already-cleaned material, where the task is to distinguish relevant content from fluent but unnecessary text.
A pattern now emerging in production pairs text-browser rendering with a lightweight model pass. One pipeline for mathematical content uses lynx rendering and then language-model cleanup to remove content it does not need and put mathematical expressions into a standard mathematical typesetting format. The broader purpose is consistent representation of equations and code where deterministic conversion is uneven. Smaller models can do this limited cleanup well. Starting with raw HTML would defeat that economy, because interpreting tag boilerplate would consume model budget otherwise available for refining semantic content.
A batch system can run another transformation as a separate step, but a live retrieval system must fit it into the time it has to return evidence. Decisions about “rules or models” depend on which residual errors justify semantic cleanup after deterministic stages have done their work.
Security risks that enter the pipeline through unclean HTML
A webpage can contain indirect prompt-injection instructions that are invisible to a human reviewer but still enter the model’s input. If those instructions are prose, Markdown conversion preserves them just as readily as it preserves the article. Format conversion cannot establish authority. The cleaning layer must therefore address not only irrelevant content but also the risk that retrieved material will be treated as instructions.
External context needs sanitization at entry, outbound rendering needs restrictions, and URL validation needs hardening. Policy gates must precede access to broad enterprise datasets, while data masking and sensitive-data protection must occur before text reaches the LLM. Post-processing arrives too late for that exposure. These controls have a different purpose from heading preservation, but they belong in the same architecture because both govern what crosses into model context. The cleaning pipeline is also the sanitization boundary.
How real-time web data delivery changes the pipeline design for agentic systems
An agent working from frozen training knowledge can act on stale facts. Live web retrieval addresses that limitation only if the returned evidence is usable when the agent needs it. A separate multi-hour cleaning job is incompatible with that requirement. For competitive research agents, brand-monitoring tools, and financial research assistants, the retrieval layer must do the cleaning. Freshness and latency become constraints on every stage.
APIs that return pre-cleaned, structured, citation-backed content offer an infrastructure answer to this constraint. They can replace several transformations that the application manages with a single retrieval call, so cleaning happens below the application boundary. The stages do not disappear. Instead, responsibility for implementing them shifts to the provider, leaving the application team to work on chunking, embedding, and prompt design.
A team using raw-HTML retrieval owns noise removal, structure normalization, serialization, sanitization, and freshness management. A team that buys structured retrieval leaves the upstream work to another system and still needs output its consumer can use. That makes the returned evidence more consequential than the convenience of the interface. Does it preserve the table relationships the task needs, and can an answer be traced to a source passage?
Deciding which pipeline design fits the job
For static or slow-moving documentation, regulatory archives, and knowledge bases, a batch pipeline with noise removal, structure normalization, and Markdown conversion is appropriate. Offline processing fits the freshness requirement. Large corpora can benefit from multi-extractor coverage, while length filtering and optional LLM cleanup address sparse pages and residual semantic noise. The consultation pipeline’s large volume of submissions illustrates the scale at which verbatim grounding and full traceability can guide staged processing. Those evidence requirements should be part of the design from the outset.
For product catalogs or financial data feeding arithmetic and sorting, schema-first typed JSON is the better fit. It bypasses the Markdown intermediate without making readable-document pipelines obsolete. By contrast, structure-critical retrieval over table-heavy or hierarchical material favors pruned HTML. The research approach preserves DOM relationships while reducing token volume, at the cost of more complex infrastructure.
For live agentic systems, purpose-built retrieval APIs returning clean, structured, cited content are an architectural fit when an in-house pipeline would demand substantial latency and freshness infrastructure. Building internally remains a choice to own those responsibilities. The design question is therefore concrete. Which stages must the team implement, which can infrastructure supply, and which relationships must survive either route? The answer defines a pipeline around the evidence the job requires, rather than around whichever conversion produces the shortest text.