Finance Research APIs That Combine Licensed Data With Live Web Intelligence
Licensed and web data together beat either one alone when arbitration resolves conflicting answers.
An AI system asked for Apple's Q3 2025 revenue can answer with total confidence and still get it wrong. Not wrong because the model made something up, but wrong because the question has more than one correct answer depending on which calendar and currency you mean. All three numbers are accurate on their own terms. Most systems pick one and hand it over without saying which definition it used, or worse, they surface all three and leave the conflict unresolved to the user.
The problem in financial AI has rarely been that the system doesn't know anything, and that failure mode is worth understanding before anything else, since a general-purpose language model grounded on web search can get close to a good financial research answer. The output still reads fine. It still comes with the tone of certainty that makes people trust it. But the arbitration that would make the number defensible never happened.
Why does this matter more in finance than in most other domains? Because the cost of being confidently wrong here is not abstract. The rest of this piece is about the architecture built to close that gap, not by making models smarter in the abstract, but by giving them a disciplined way to resolve exactly this kind of conflict before they ever answer.
Why no single traditional data source can fix this
One might argue the fix is simple: just use a licensed data feed instead of a general-purpose model, and the conflict disappears. It doesn't, because the financial data market is split into distinct product categories, and each one was built to solve a different problem, not this one.
Market data APIs, the structured, ticker-keyed feeds built for prices and exchange data, are accurate and fast. They were never designed to take a natural-language question and figure out what the asker actually meant. Web data APIs pull in a wide, current sweep of documents and pages, but they hand back raw, unreconciled text. Research APIs close part of that gap by synthesizing a reasoned, cited answer, which makes them well suited to investment analysis, due diligence, and competitive intelligence questions that draw on multiple sources. But they trade away speed to do it, making them a poor fit for live prices or simple metrics, where a few hundred milliseconds decides the answer's usefulness more than a few paragraphs of reasoning would.
Then there are the licensed structured feeds themselves, sources like S&P Global, SEC/EDGAR, FRED, BLS, QUODD, and NASDAQ. These are about as authoritative as financial data gets, and their definitions are fixed and well documented. Macro series in particular follow official release calendars: BLS, BEA, Eurostat, and similar agencies publish on fixed cadences, and no API, however well engineered, can show a GDP revision before the agency itself releases it. That's a real constraint rather than a shortcoming of any particular vendor, so any fair evaluation of these tools has to account for it.
Placed side by side, those three categories reveal the shape of the actual problem. It's an arbitration problem: knowing which number, from which source, answers the exact period, unit, and definition the question specified, rather than a coverage problem that more sources would fix. No single category above does that job on its own, because none of them was built to.
The hybrid architecture: licensed data, live web, and evidence arbitration as one layer
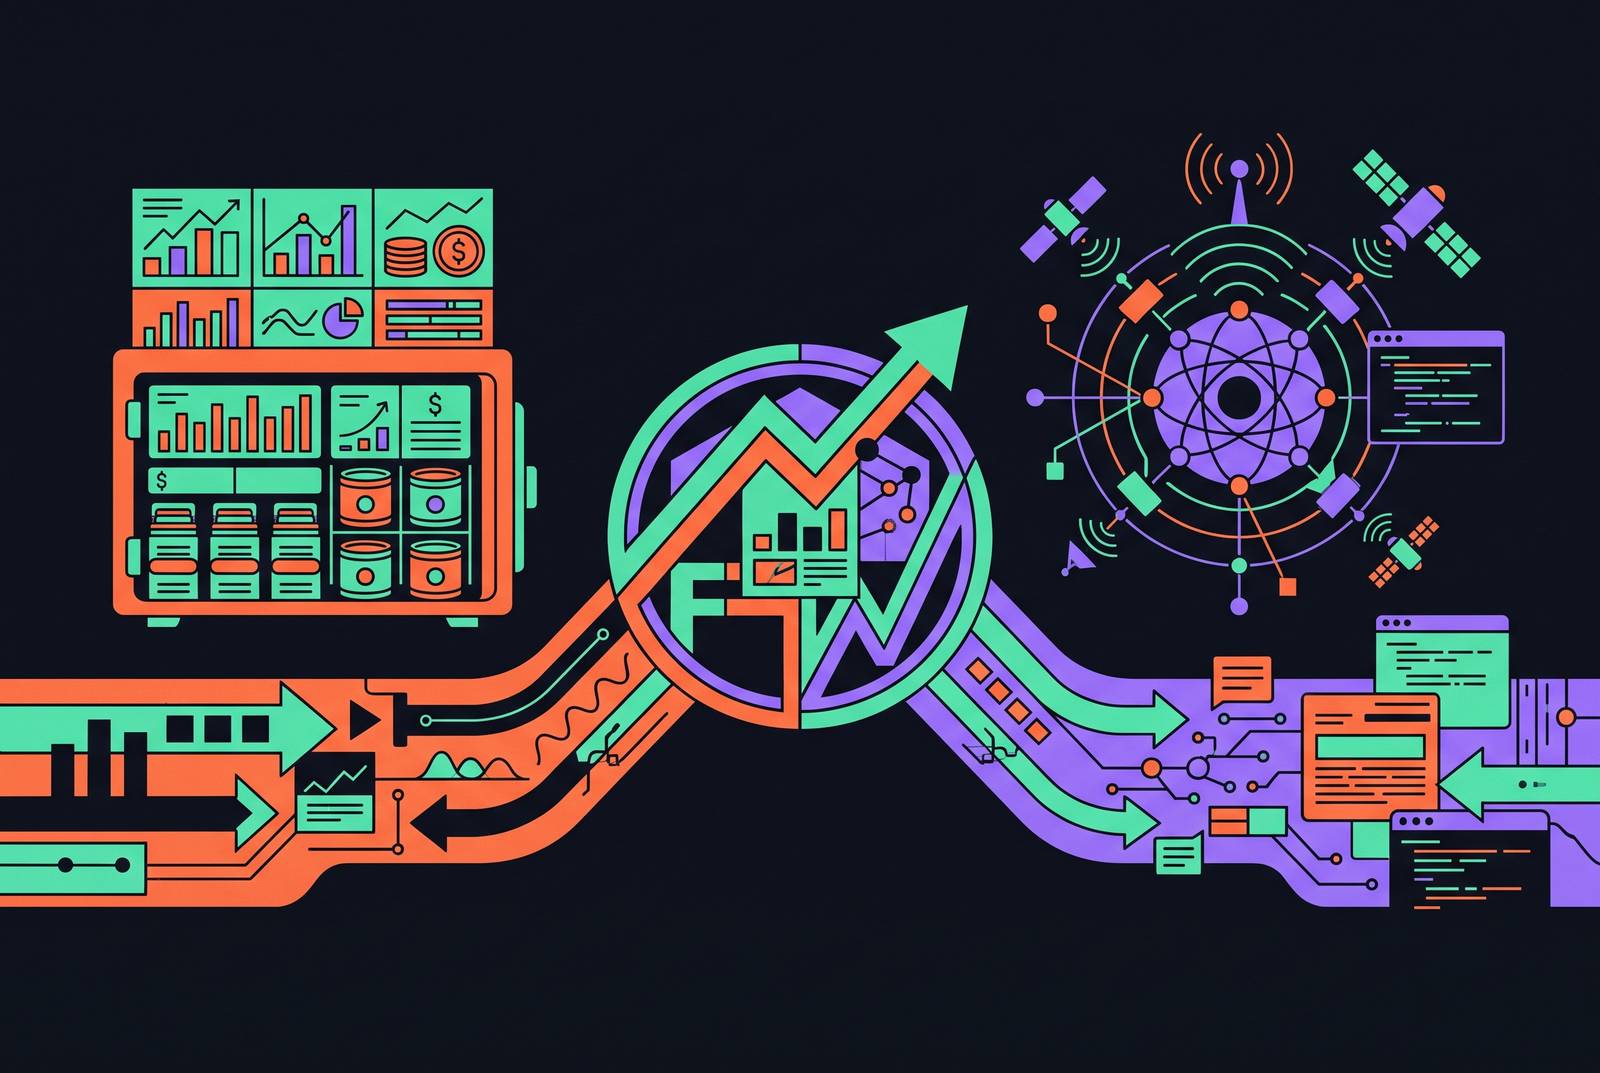
A Finance Research API attempts to resolve conflicting data by arbitrating between sources directly, and the architecture behind it looks different from a data aggregator. Rather than stitching feeds together and letting the caller sort out the conflicts, it functions as an orchestration layer: licensed structured data and live web intelligence feed into a single reasoning process, and that process runs evidence arbitration before it ever returns an answer.
Take the version described in You.com's Finance Research API announcement as a concrete example of how this gets built. The licensed data spine covers four categories of information. Public-company filings, including revenue by segment, contractual obligations, footnote values, debt tables, and fiscal-year disclosures, come from S&P Global, SEC/EDGAR, and investor-relations sources directly. And derived calculations, ratios, growth rates, percentage shares, unit conversions, and cross-source comparisons, run only after every input they depend on has been retrieved, aligned, and cited.
Layered on top of that spine sits live web intelligence: regulatory filings, central bank statements, earnings coverage, and sector analysis published since the licensed feed's last update. The two layers aren't duplicating each other. Evidence arbitration is the step that makes the combination trustworthy rather than just comprehensive: before returning a figure, the system matches the exact period, unit, source, and definition the question implies, and discards candidate answers that technically respond to a different version of the question, even if they looked plausible on first pass.
What comes back to the developer is a JSON object: a markdown-formatted answer (the content_type field is always text), inline citation tags, and a sources array that maps every citation to a URL. The reasoning behind the number is auditable rather than hidden inside a black box. On the access side, the pattern is just as deliberate: a developer sends a single POST request with a financial question and a research effort level, and the orchestration layer handles routing to the relevant licensed sources behind that one call. Nobody has to wire up a dozen separate provider integrations to ask one question. That access pattern is also shifting at the protocol level. The REST call is giving ground to the Model Context Protocol, which lets an AI agent discover and call financial data endpoints on its own rather than requiring a developer to hard-code every integration in advance, which is the direction this category is moving.
What the FinSearchComp benchmark measures
Every vendor in this space makes an accuracy claim, and almost none of those claims can be checked from documentation alone. That's exactly the gap a domain-specific benchmark is supposed to close, and in financial AI, that benchmark is FinSearchComp.
FinSearchComp splits its evaluation into three tiers, and each maps to a workflow a developer would actually build. T1 covers time-sensitive live data retrieval, the kind of query where latency and freshness decide the answer's usefulness more than depth does. T2 covers simple historical lookup: well-defined questions with one correct answer sitting in a licensed source. T3 covers complex historical investigation, multi-step queries that require reasoning across many sources over extended time periods. The distinction between tiers isn't academic. Anyone comparing vendors should match the tier they're reading about to the workload they actually plan to run, rather than treating a single benchmark number as a verdict on the whole product.
The published results so far tell a tiered story rather than a single winner. Perplexity Finance Search was evaluated on FinSearchComp's T1 tier and came out with the highest accuracy for live financial data in its cohort, along with the lowest cost per correct answer on T1 queries specifically. On FinSearchComp specifically, You.com's Finance Research API ranks first on the T2 Simple Historical Lookup sub-task, a result the company states publicly as its primary performance claim.
None of this settles the question of which system is best overall, because that question doesn't have a single answer. One might reasonably ask whether a benchmark that measures well-scoped lookup and investigation tasks captures everything a financial analyst actually needs, and it doesn't quite. Benchmarks in this category move quickly enough that any lead one vendor holds today should be read as a snapshot, not a settled ranking. A team evaluating these tools six months from now should expect the leaderboard to have shifted.
Where this architecture performs well
The honest version of this architecture's story has two halves, and skipping the second one would make the first half a sales pitch rather than an analysis.
The fit is strong for due diligence and competitive intelligence work, where a question requires pulling from many sources across time and the resulting answer needs to be citable, not just plausible. It's equally strong in multi-step agentic workflows, where one agent's output becomes another step's input and that intermediate result needs a citation attached to it so the chain stays auditable all the way through. The structured JSON output with inline citations exists for exactly this kind of handoff.
But what if the query doesn't need any of that depth? Latency-critical use cases expose the real cost of the architecture: deep, exhaustive queries, particularly multi-step investigations that run parallel research branches and cross-source verification, can take minutes to complete. That's not a bug a future engineering sprint will quietly fix. The macro-data publication lag is a second, structural limit: the API cannot show a BLS, BEA, or Eurostat figure before the agency itself releases it, because that schedule belongs to the agency, not the vendor.
The strongest challenge to this whole architecture comes from a fair question: if a general-purpose model grounded on web search is cheaper and faster, does the accuracy gain from a Finance Research API justify its cost? T1-style live-price lookups, where milliseconds decide the use case, and simple single-source lookups that don't require resolving any conflict, are exactly the queries where the lighter, faster approach wins. The split is to route the queries that need arbitration and citation to a Finance Research API, and route live prices and simple metrics to a faster, lower-latency feed built for that job. Testing against the specific distribution of queries a given product actually generates tells a developer more than any leaderboard position will.
The compliance and security requirements that apply to financial AI agents in 2026
For a team operating in a regulated environment, the compliance posture of a Finance Research API vendor carries as much weight as its benchmark score, and several of the relevant requirements are no longer optional or theoretical.
SOC 2 Type II certification is the baseline a regulated buyer should expect, and the distinction from Type I matters: Type II covers a sustained operating period rather than a single point-in-time snapshot, which is the standard regulators and enterprise security teams actually want to see. Any agent built on a Finance Research API that surfaces its output to end users sits within that scope, which makes this a live compliance question for 2026 rather than a future one.
Data handling at the vendor layer deserves the same scrutiny as the data itself. An organization needs to understand and document how its chosen API provider uses, retains, and protects the data passing through it, and whether contractual safeguards back up those practices. Zero data retention paired with SOC 2 certification at the infrastructure layer changes the calculus for enterprise buyers: licensed-data accuracy no longer has to come bundled with the data-handling trade-offs that have historically kept AI tools out of regulated environments. That combination, accuracy without the retention risk, is one of the more meaningful differentiators available to a buyer comparing vendors in this space right now. Teams working with sensitive financial workloads should also look closely at the provenance and potential bias of any supplementary datasets a vendor uses as supporting evidence before that evidence ends up cited in a client-facing output.
Criteria for choosing a Finance Research API for an agentic workflow
Everything the previous sections established, multiple correct answers that require arbitration, the hybrid architecture that resolves them, the benchmark tiers that measure accuracy, and the compliance requirements that govern disclosure, points toward a short list of criteria that matter more than a feature chart or a pricing page.
Licensed data coverage and provenance come first. The question to ask isn't whether a vendor has "financial data" but which specific institutional sources sit inside its data spine, and whether those are the same sources financial professionals already rely on rather than scraped approximations of them. You.com's Finance Research API, for instance, draws on S&P Global, SEC/EDGAR, FRED, BLS, BEA, Eurostat, the World Bank, the IMF, the OECD, the EIA, QUODD, and NASDAQ, a spine built from the same institutional sources that already anchor professional financial research rather than a layer of secondary aggregation sitting on top of them.
Evidence arbitration transparency matters just as much: does the API disclose which source, period, and definition it used, or does it hand back a number without showing its work? The output format follows directly from that question. A structured response with inline citations and a sources array mapping each claim to a URL lets a developer audit a chain of reasoning rather than trust it blindly, which matters most in exactly the multi-step agentic workflows this architecture was built for. Benchmark performance on the right tier is the fourth criterion, and the key word is "right": a T1 result says something about live-data accuracy, a T2 result says something about historical lookup, and a T3 result says something about complex investigation, so matching the benchmark to the actual workload tells a developer far more than a single aggregate score would. Compliance posture closes the list: SOC 2 Type II certification, documented data-retention practices, and clarity on how the vendor handles EU AI Act transparency obligations decide whether a tool can be deployed in a regulated environment, independent of how well it scores on any benchmark.
None of these five criteria substitutes for testing a vendor against the specific distribution of questions a given product will actually ask. Together they give a developer a way to gauge whether an API has actually done the arbitration work to earn its confident tone.
Sources
- You.com
- FinSearchComp: Towards a Realistic, Expert-Level ...
- Confidently Wrong: Detecting Hallucinations in Financial Question Answering from LLM Internal States
- AI Agents in Financial Markets: Architecture, Applications, and Systemic Implications
- Client Alert: Generative Artificial Intelligence in Financial Services: A Practical Compliance Playbook for 2026 - Shumaker, Loop & Kendrick, LLP
- Bayesian RAG: uncertainty-aware retrieval for reliable financial question answering