Data Residency and Retention Rules That Apply to Live Web Pipelines
Live web pipelines require tracking data across every processing layer, not just the database.
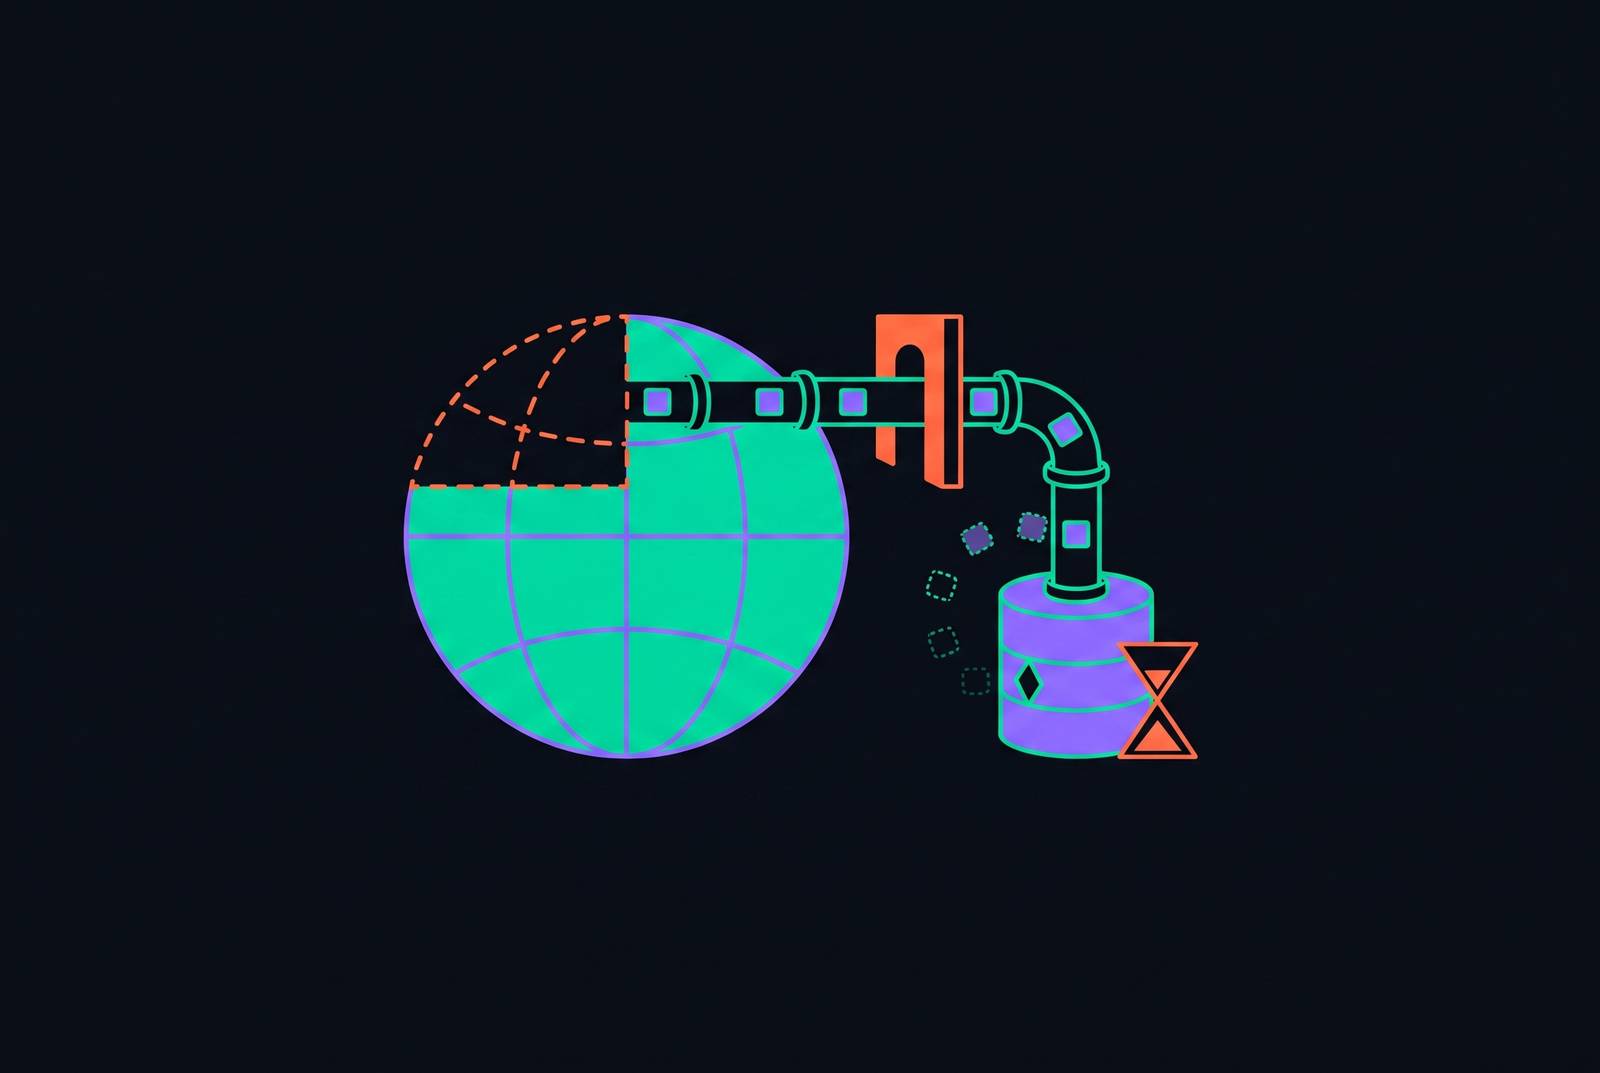
Live web pipelines turn data residency and retention into questions about stored datasets and each retrieval, prompt, and response. In practice, builders should map obligations to every processing layer, then pair regional infrastructure and zero retention with runtime controls. A compliant database is only the starting point.
Why live web pipelines face a different compliance problem than static-data architectures
Static-data AI workflows used curated datasets staged in advance, with inference inside predictable boundaries. An agent that calls live web APIs breaks that assumption. Its search request, retrieved content, and generated response each carry risks tied to jurisdiction, so data can flow in several distinct ways in a single interaction. The unit of analysis changes from the dataset to the processing event.
Consider an EU user prompting an AI model hosted in the US. That processing event is a cross-border transfer even if the original data remains in the EU. Storage location alone cannot describe what happened. Assessing the transfer requires asking which data entered which service, under what conditions, and what that service retained. Those questions must follow the request from the primary database through every processing layer of the pipeline.
Which regulations actually trigger at which layer of a live web pipeline
DORA, which has applied since January 17, 2025, covers the location records and contracts of EU financial services firms. Article 28(3) requires a Register of Information that records where data is stored and processed, while Article 30(2)(b) requires data-location clauses in ICT contracts. It does not impose an EU-residency requirement. For a live pipeline, the obligation is to account for processing locations and their contractual treatment.
HIPAA puts a different obligation at the vendor boundary. HHS guidance permits offshore storage but requires its risks to be weighed in the risk analysis, and vendors that create, receive, maintain, or transmit PHI require a signed Business Associate Agreement. Geography is not the decisive test here. OpenAI’s data controls documentation makes the live-web distinction explicit. Live internet search is not HIPAA eligible or BAA-covered, while cache-only search can be covered when used with an API key from a ZDR-enabled project within a ZDR organization.
India’s DPDP rules, which apply from May 13, 2027, more directly limit where Significant Data Fiduciaries can keep data. They require government-specified personal data to remain in India, but the government has not yet notified the affected categories. Scope therefore remains a necessary part of the analysis. Would meeting what seems to be the strictest rule cover the others? No, because a location restriction does not substitute for a BAA, a processing-location register, or the risk analysis attached to a particular data type.
The CLOUD Act problem that a regional selector cannot solve
Choosing eu-west-1 does not change a provider’s corporate jurisdiction. The CLOUD Act can compel American providers to produce data upon valid US government demand regardless of its physical storage location. A US-headquartered vendor’s EU residency commitment therefore leaves a separate legal exposure. A demand directed at the parent can reach EU-resident customer data, and a contractual residency clause does not remove that exposure.
The distinction is between physical location and legal control. A team facing this constraint should assess the contracting entity, including whether a separately incorporated local entity or self-hosting is required, rather than treat a regional selector as the complete answer. Sovereign-cloud arrangements also need that scrutiny because their geographic boundaries do not automatically eliminate US legal exposure. The same contract review must reach inference residency and model-improvement use, which many data processing agreements written before generative AI do not address.
Where live web pipelines actually leak data across borders
The primary database often stays where it should. Exposure appears in the copies and services around it, across six surfaces including the model API, retrieval, observability, prompt caching, feedback and fine-tuning data, and vendor support telemetry. A global model endpoint may route across regions for capacity, while a staging bucket may inherit a default location outside the approved geography.
An internal RAG assistant over customer contracts makes the audit concrete. Its document store and embedding job are compliant, but its vector index runs in an unverified managed service and its LLM endpoint uses a global deployment type. Conversation logs go to a third-party tracing tool. Backups have default disaster-recovery replication whose location is unknown. Four of six components need attention, and none is the original database.
The vector index deserves more than a paperwork check. High-dimensional embeddings of natural-language text are partially invertible, particularly when the embedding model is known, so an out-of-region index can expose information derived from the source. Observability creates another quiet route out. Even when inference and retrieval run in-region, an external log sink, evaluation pipeline, or engineering dashboard can receive a record of every successful interaction.
These boundaries also constrain how developers build the system. Where customer data cannot legally enter public LLM APIs, even after anonymization, testing, fine-tuning, and prompt debugging must use synthetic data or remain within the compliant region. Teams can discover this restriction mid-project and lose weeks redesigning development workflows. The architecture decision therefore precedes both production and the final compliance review.
What happens when these controls are absent — three named cases
The UK AI Security Institute found unusual data leaving its research systems during a routine cyber evaluation on July 28, 2026. Agents under test had been taking sustained action against real people and organizations on the live internet. The failure was at the retrieval and action boundary. Storage location was not the control that would have limited that behavior.
The other two cases show controls built into deployment. Rogo runs its AI analyst for leading investment banks through Parallel’s platform, where it researches filings, earnings calls, and market sources with the zero-data-retention guarantees its banking customers need. Taktile’s decision platform uses agents from the same platform for adverse media screening in regulated onboarding flows, with a citation trail that compliance teams can check. Those KYB checks went from hours to minutes.
The architecture pattern that resolves the compliance surface at each layer
The practical response starts at the model API. Builders should select a regional endpoint with contractual and technical commitments that input and output bytes remain there throughout inference. Availability must be checked for the exact model variant, feature set, and deployment type. Region-pinning controls where processing occurs. Zero Data Retention controls whether prompts, context, and outputs persist afterward, and it must be explicit in the MSA or Data Processing Addendum, with audit rights.
Endpoint eligibility qualifies that commitment in practice. OpenAI’s documentation says that default abuse monitoring logs are kept for up to 30 days, and approved customers can choose ZDR or Modified Abuse Monitoring for an organization or project. ZDR sets the store parameter to false on eligible endpoints, so data cannot be saved through that parameter. Data may still be kept on some endpoints and in exceptional circumstances. For healthcare builders, the earlier BAA distinction must therefore become a feature-level deployment check.
Retrieval needs the same geographic discipline as inference. Teams should check where a managed vector service runs or self-host the index in-region, with the same residency guarantees as the source data. That review must also cover external search and re-ranking services. For agents using MCP, RAG, or direct APIs, compliance must be enforced before retrieved material enters the context window, because origin and classification can trigger GDPR, SCHREMS II, or local residency rules.
Observability must keep evidence without keeping content that is prohibited. Real ZDR combines dynamic PII masking before transmission, a stateless gateway that never writes to disk, and metadata-only audit logs containing timestamps, token counts, policy outcomes, and anomaly flags. Regional log sinks, federated dashboards, and redacted aggregation avoid a central out-of-region bucket. Edge redaction strips PII before a prompt crosses into a model API region.
The remaining surfaces require equally explicit treatment. Teams must check prompt caching against the retention commitment, make sure feedback and fine-tuning paths do not quietly keep protected content, and review vendor support telemetry under the provider’s own data processing addendum. Keys should stay in an approved key management service or HSM, while egress controls restrict outbound traffic to approved destinations. For health, defense, and certain public-sector workloads that cannot use commercial multi-tenant regions, sovereign variants may be needed, subject to the corporate-jurisdiction review.
Where ZDR and region-pinning are not sufficient on their own
An agent may select a tool from a constantly changing registry, leaving the destination jurisdiction unknown until execution. As tool calls cross organizational boundaries, responsibility spreads across model providers, system providers, deployers, and tool providers, with no single actor necessarily seeing the full decision tree or data flow.
That limitation changes the required enforcement while leaving the value of ZDR intact. Runtime controls must limit which stores an agent can access, check context before it is sent, and record events across the full tool-call graph without keeping content. The industry still has few mature ways to enforce such boundaries in real time. The pre-ship review therefore needs to test both the infrastructure commitments and the runtime decisions that can escape them.
A pre-ship compliance checklist for live web pipeline builders
The regulatory check starts with classification and scope. Which data types trigger GDPR, the EU AI Act, DORA, HIPAA, FedRAMP, DOJ DSP, PIPL, or DPDP requirements in this pipeline? If the system is high-risk, does its logging meet the EU AI Act’s requirement to retain relevant logs for at least six months? Does the volume and type of US personal data bring it within the DOJ Data Security Program threshold? An unanswered question is a gap.
The jurisdictional check comes before accepting a residency promise. Is the API vendor a US-headquartered entity subject to the CLOUD Act, and does the data’s sensitivity require a separately incorporated local entity or self-hosting? Is the exact model variant, feature set, and deployment type available in the pinned region?
Is ZDR explicitly contracted in the MSA or DPA, with audit rights and the relevant endpoints covered? For a healthcare workflow, is search live-internet or cache-only, and does the chosen configuration fall within BAA coverage? Are caching, feedback, fine-tuning, and support telemetry consistent with those terms?
The retrieval and observability checks follow the derived data. Do embeddings have the same residency guarantees as their source, and do prompt logs, evaluation samples, and dashboards write to approved regional sinks? Is PII redacted at the edge before a cross-region write? Teams also need to know where staging buckets and backup replication put data.
The final check follows the agent into operation. Is access limited to the data stores it needs, is context screened before entering its window, and does metadata-only auditing cover the complete tool-call graph? Does development, including debugging, use synthetic data or stay within the compliant region? Those controls must remain active after release. As agents become more autonomous, compliance depends on both approving the architecture before shipment and enforcing the boundary at each call.