Citation Quality as a Search API Evaluation Metric
Users only click links, making citation validity the true test of production readiness.
A citation is the one piece of an AI agent's output that a user actually checks. Everything else, the confidence score, the aggregate groundedness number, the internal reasoning trace, stays invisible to the person reading the answer. That asymmetry is why citation quality has quietly become the measure that decides whether a search API is production-ready, and why this piece treats it as the central axis of evaluation rather than one metric among many. A user who clicks a link and gets a 404, or lands on an outdated blog post in answer to a question about recent events, has learned something about the system that no dashboard will show them.
Citation quality as the decisive axis in search API evaluation
The bottleneck for production AI agents was never really about model quality. Users click URLs. They do not read confidence scores, and they do not open up a groundedness dashboard to check whether the retrieval pipeline behaved.
FutureAGI's 2026 evaluation framework names the problem directly: standard RAG evaluation was built for a frozen vector store sitting next to a stable ground truth, and search-augmented agents have neither of those things. The citation is the one artifact a user actually checks. These three differences pull search-augmented evaluation out of the RAG category entirely, so metrics built for a static knowledge base still pass agents that cite dead or outdated pages.
How citation failures reach production past standard eval metrics
A search agent can post a healthy groundedness number and score well on context adherence, but its citations can still point nowhere useful. It is the failure pattern that slips past teams who trust aggregate scores to catch problems before launch. Deep research agents chain multiple searches and synthesize across them, so they generate far more citations per query than a simple search-augmented LLM does, and they hallucinate URLs at a higher rate. More citations per answer means more surface area for a fabricated or broken one to slip through unnoticed.
FutureAGI's framework identifies the root cause: it says nothing about whether the citation the agent actually emitted is a real URL, whether that URL resolves when a user clicks it, or whether the passage at that URL actually contains the claim being attributed to it. Those are three separate failure points, and an aggregate groundedness score collapses all three into a single number that can look fine even when one of them has failed.
Staleness deserves the same weight as outright hallucination, because the effect on trust is identical. The link works. The page it points to does not contain the answer. Neither of those outcomes required a model to be unintelligent. They required a citation trail that nobody checked carefully enough before the answer went out the door.
The four evaluation axes that catch what aggregate scores miss
FutureAGI's 2026 framework scores search-augmented agents across four separate axes: query quality, source freshness, source diversity, and citation validity. The framework's argument is that these four numbers need to be reported per query rather than averaged into one score, because averaging hides which axis broke down on a given task.
Query quality is the first axis, and it checks whether the search query an agent writes for itself preserves the actual constraints in the user's question. Consider a user asking for laptops with battery life above a specific threshold. If the agent's query rewriter compresses that request down to something generic like "best laptops 2026 for ML," the retrieved answer can still score well on groundedness, because the answer is consistent with whatever got retrieved. The battery life constraint simply vanished somewhere between the user's question and the search string, and groundedness has no way to notice that loss.
Source freshness is the second axis: it scores each source's recency against how time-sensitive the question actually is. Braintrust's September 2026 guide to web search providers lists freshness controls (publication-date filters, recency windows, cache-age settings) as one of seven criteria worth checking before picking a provider, precisely because staleness is a citation quality failure and not a separate, lesser concern.
Source diversity is the third axis, measuring how spread out the domains are across everything an agent retrieved for a given answer. The failure mode is citation monoculture: three sources cited in an answer, all three pulled from the same single domain. Rubric anchors for this axis include the count of unique domains represented, a cap on how many citations can come from any one domain, and the ratio of primary sources to secondary ones summarizing those primary sources.
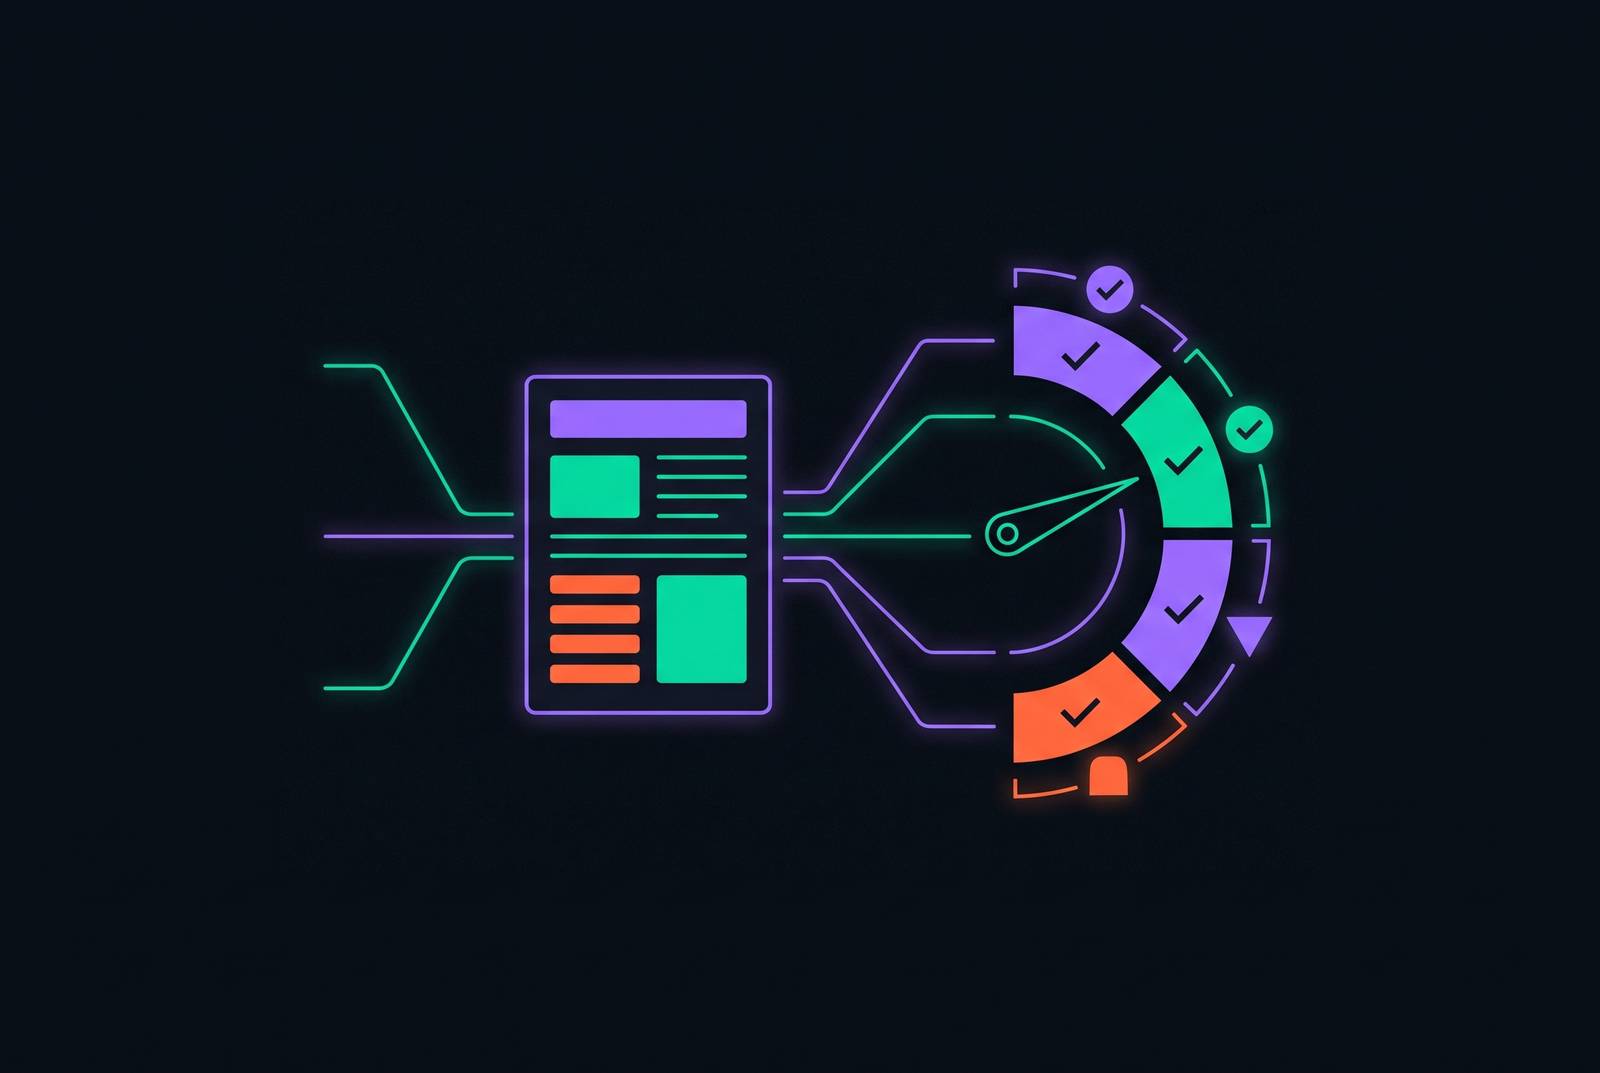
Citation validity is the fourth axis, and it checks three things in sequence: whether the URL resolves, whether the passage being cited is actually present on that page, and whether that passage supports the specific claim attributed to it. FutureAGI describes this check as the single highest-signal cheap check in the whole category, noting that teams who wire it into their pipeline stop seeing the "user clicked a 404" failure mode almost immediately.
None of this replaces the standard RAG metrics that already exist. Groundedness, ContextAdherence, FactualAccuracy, and Completeness still run alongside the four axes, and they remain necessary. Score each axis per query and look at the full vector instead of collapsing it into one number, because a single aggregate score hides exactly which axis collapsed on a given task.
How citation quality requirements vary by domain
Financial services and legal work carry more exposure to citation failure than most domains, because people act on these outputs instead of just reading them, and both fields attach real liability to whatever gets cited. Systematic studies of legal AI systems have found false citations appearing in a substantial share of responses, and the Q1 2026 sanctions against legal professionals for AI-fabricated court citations are a direct consequence of that gap between output and verification.
Finance shows a related but distinct pattern: a real gap between how much automation has been adopted and how reliably it actually executes. Redwood Software's survey of 300 financial services professionals found that three of the top four challenges firms report tie back to data pipeline and cross-system coordination, and citation pipelines sit squarely inside that bottleneck. A citation that needs to move from a search layer through a synthesis layer and into a client-facing report has to survive every handoff in that chain intact.
Several firms have built their architecture around this requirement rather than treating it as an afterthought. Morgan Stanley's AI @ Morgan Stanley Assistant, built with OpenAI on GPT-4, gives financial advisors access to a large corpus of research documents and a significant gain in retrieval efficiency, and that efficiency gain still requires every response to trace back to a document that can actually be cited.
One might ask why this matters beyond these specific firms. The risk compounds when agents operate outside the view of the teams meant to be governing them. McKinsey reporting cited by Parallel notes that a large majority of organizations are already reporting risky behavior from AI agents operating without central IT or compliance oversight, and a shadow agent of this kind can issue citations drawn from data sources no governance team ever reviewed or approved. Unreliable citations, in other words, are not confined to what a single well-built agent does; they extend to the agents nobody is watching.
What search API design choices determine citation quality
Citation quality at the output layer is set upstream, by decisions made at the provider level long before an agent ever writes a query. Five design choices do most of the work: what metadata the API returns, how freshness is controlled, whether content extraction is bundled with search, how source diversity is managed, and whether the URL returned in the response matches the URL actually on the page.
Metadata completeness comes first. If a date field was never returned, a model cannot use it to validate a citation.
Perplexity Sonar's response structure is often pointed to as a reference design for this problem. Every response carries a top-level citations array containing URLs, alongside a separate search_results array that includes title, URL, date, and snippet, with the model citing inline against both. That structure is held up as something close to a gold standard for showing sources in a verifiable way.
Freshness controls, the second design lever, are not a cosmetic feature. Without those controls, there is no way to check whether a cited source actually meets the recency bar a question demands.
Content extraction is the third lever. AI-native search APIs that return query-relevant excerpts or full-page Markdown in the same call that returns the URL let a team check whether the cited page actually supports the agent's claim without firing off a second request. SERP-style APIs that hand back only a list of links push that entire verification cost onto the agent, and by extension onto whoever is building the evaluation pipeline around it.
Independence of the underlying search index matters too. Running an independent index affects both how fresh results can be and what ranking signals feed into citation quality, because the provider is not inheriting someone else's ranking decisions along with the data.
Token efficiency turns out to be tied to citation quality in a way that is easy to miss. Braintrust's guide notes that context budget pressure, coming from MCP tool descriptions and the volume of retrieved content competing for space in the same window, can force an agent to truncate or drop citations outright when it runs short on room. APIs that enforce per-result character limits and trim content at the section level help preserve citation fidelity even under tight token constraints, rather than leaving it to chance which citations survive a truncation pass.
Data governance is the fifth and final lever, and it is inseparable from citation-trail design at the architecture level. In multi-agent setups, data collected by one tool is often passed along to downstream agents as context, and under major PII frameworks that handoff can constitute unauthorized disclosure if it is not designed with that risk in mind. You.com's Web Search API and Answer API are built around this cluster of requirements: structured outputs with verifiable sources, real-time freshness, and zero data retention at the enterprise tier. Those choices are what make the four-axis framework something a team can actually score against, rather than a standard that sounds good on paper but has no API behind it capable of supporting the checks.
How independent benchmarks measure citation quality
Independent benchmarks give you a more reliable read on citation quality than vendor-published numbers, if only because a vendor's own benchmark tends to use whatever model, prompt set, and question list makes its own product look best. Braintrust is candid about this dynamic in its own guide, noting that vendors design benchmarks to make themselves look good, and adding that its own publication is no exception, so readers should weigh it with that in mind.
But independent benchmarks carry a limitation of their own that is worth taking seriously rather than waving away. The rank order of the four systems being evaluated did not hold steady between those two snapshots either. What looks, on the surface, like a measurement of a model's citation quality is in some cases a measurement of the verification oracle checking that citation, not the model producing it.
That finding should temper how benchmark rankings get used, without discarding them. What rank order within a narrow performance band cannot be trusted to do is hold steady across different verification snapshots, since the same underlying research found that retrieval grounding cuts citation hallucination by 75 to 90 percent across frontier models. Whether a provider's architecture grounds its responses in retrieved content at all matters more than exactly where it lands in a tight percentile band against a benchmark that might shift under a different oracle snapshot next quarter.
Public, reproducible benchmarks on domain-specific tasks still carry weight for this reason. You.com's Research API previously held the top position on the DeepSearchQA benchmark, a position since surpassed by other systems as the field moved forward, and its Finance Research API currently ranks first on FinSearchComp's historical lookup sub-task, known as T2, a result specific to a domain where citation accuracy is one of the primary things being scored. Results like these describe one snapshot in a field that keeps moving.
A practical evaluation workflow for citation quality in production
If you treat citation quality as a first-class production metric, you run evaluation continuously rather than only when a provider gets integrated, because the live web keeps changing the ground truth underneath a static test suite. A workflow built for this starts with provider selection and ends with ongoing per-query scoring, a continuous process rather than a one-time check at launch.
The first step is choosing a provider based on metadata completeness and freshness controls before anything else gets evaluated. Independent benchmarks help with shortlisting and with catching large gaps between providers, with the oracle-dependence finding in mind as a reason to run evaluation on actual production workloads rather than trusting a single published ranking to hold steady over time.
Citation validity checks need a source of continuously refreshed web data to validate against, because a static reference corpus goes stale the same way the citations it's meant to check can. Whichever provider a team settles on, the four axes give a way to see exactly where an agent's citation behavior is breaking down, rather than trusting a single aggregate score to tell the whole story.